Parallel solvers (MPI)
The 3-D Yin-Yang Stokes solver also runs under MPI, with the two patches and, optionally, sub-blocks of each patch on separate ranks. A run uses 2 × mpiNr × mpiNt × mpiNp ranks in total. The serial path (cfg.useMPI = false) is the default. 2-D runs need no MPI flag: MUMPS initialises MPI on one rank by itself, and there is no 2-D domain decomposition (validate! refuses useMPI = true with dim = 2).
The MPI paths are driven by bin/run_mpi.jl and exercised by the tests/test_mpi_*.jl files, which need mpiexec and are not part of tests/run_tests.jl. Launch with
./bin/mileva run-mpi -n 2 my_parameters.jlThe dispatcher
solve_stokes_distributed!(lg, ETA_local, buoy_local, cfg, ri; mode = :auto, n_schwarz = 5, max_iter = 200, restart = 30, tol = 1e-6) in solvers/solve_stokes_distributed.jl is the single entry point. Every physics term reaches it through the distributed assembly, so a model that runs serially runs through the dispatcher unchanged. The mode keyword selects a tier; :auto picks by rank count and
| Mode | Function | What it does | :auto picks it when |
|---|---|---|---|
:serial | multigrid_stokes | serial Yin-Yang solver | 1 rank |
:phase_a | multigrid_stokes_mpi! (solvers/multigrid_stokes_mpi.jl) | one rank per patch, each running FGMRES + V-cycle, Schwarz exchange with MPI.Sendrecv! | 2 ranks |
:direct | distributed_stokes_phasebpp! | MUMPS distributed LU with distributed matrix input (row slabs per rank); assembly replicated on every rank | |
:b4p | distributed_stokes_phaseb4p! | MUMPS distributed LU with a truly distributed assembly (stokes_assembly_3d_local.jl) and a factor cache across steps | explicit only |
:iter | distributed_stokes_fgmres! | distributed FGMRES with a block-Jacobi preconditioner (per-rank UMFPACK on the diagonal block) | |
:rich | distributed_stokes_iterative! | damped Richardson with the same block-Jacobi preconditioner | explicit only |
For 3-D convection runs, :phase_a is the path the examples use: it is the serial algorithm with the two patches on two ranks and the wall values exchanged by message passing instead of memory.
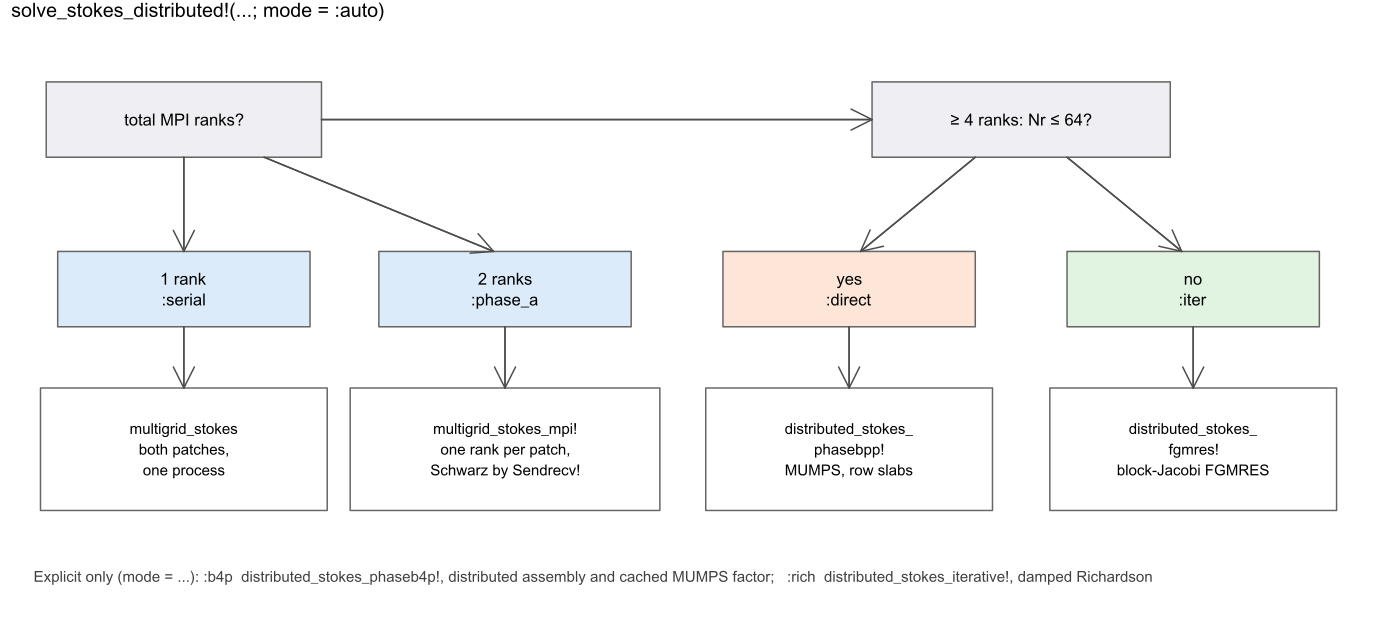
How mode = :auto chooses a tier in solve_stokes_distributed!, with the thresholds as coded: the total number of ranks first, then the radial resolution of the patch. The two tiers at the bottom are reached only when named explicitly. Script: docs/scripts/solvers_parallel_sections.jl.
Memory per rank
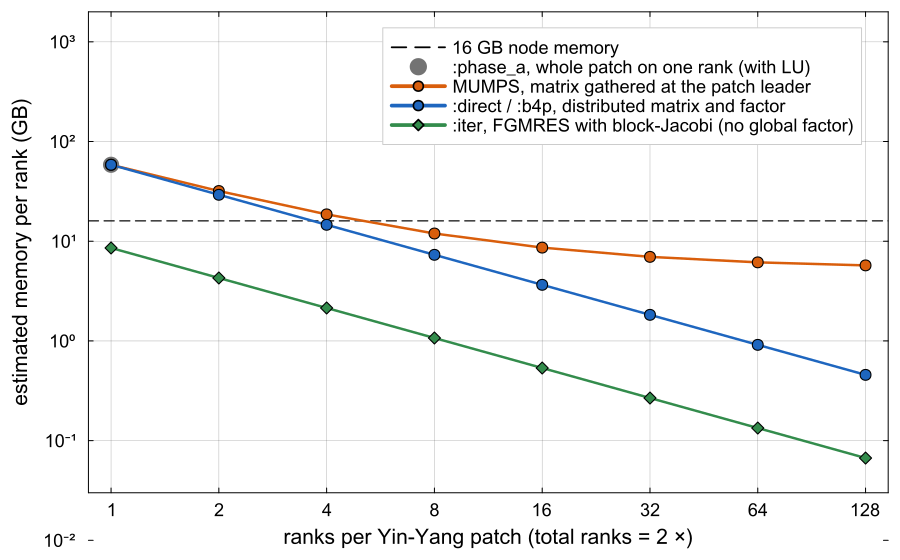
Estimated memory per rank for a grid of estimate_dofs_raw (utils/dof_estimator.jl). The model assumes about 50 nonzeros per row, a LU factor ten times the matrix and an FGMRES basis of 60 vectors; it does not count the block-Jacobi factors of :iter. With the matrix gathered at the patch leader the leader's share stops falling; with distributed input and factor (:direct, :b4p) it falls as the inverse rank count. Script: docs/scripts/solvers_parallel_memory.jl.
estimate_dofs(cfg; n_ranks_per_patch, ram_per_rank_gb) prints the same numbers for a configuration and recommends a mode. The direct tiers scale to a few million unknowns per patch, set by the MUMPS factor. The iterative tiers avoid a global factor, but their block-Jacobi preconditioner factorises each rank's diagonal block with UMFPACK, which limits blocks to about
Distributed assembly
assemble_stokes_3d_local is a structural copy of assemble_stokes_3d restricted to each rank's owned cells, reading viscosity and buoyancy from halo-padded local arrays (parallel/local_grid.jl, parallel/halo_3d.jl). The reference viscosity is reduced across ranks so every rank scales its rows identically. Any physics term added to one assembly must be added to the other; tests/test_assembly_3d_mirror.jl checks on a single rank that the two agree to useCurvatureTerms.
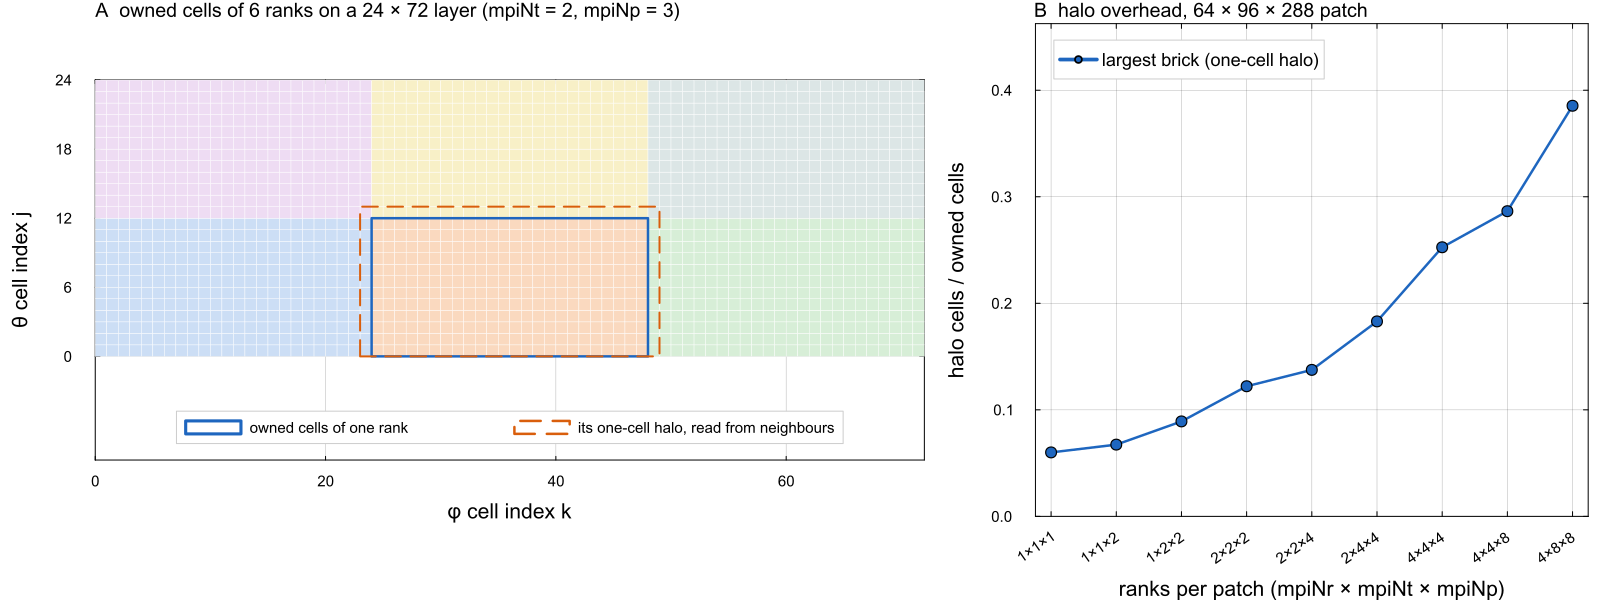
(A) The cells each rank owns on one radial layer of a 24 × 72 patch split mpiNt = 2, mpiNp = 3, from the block decomposition _range_for that mpi_init! uses; the dashed outline is the one-cell halo one rank reads from its neighbours (clipped at the patch walls). (B) Halo storage over owned cells for the largest brick of a 64 × 96 × 288 patch, as LocalGrid3D pads every face: 6 % on one rank, 25 % at 64 ranks per patch and 39 % at 256, the surface-to-volume cost of decomposing further. Script: docs/scripts/solvers_parallel_sections.jl.
Two further distributed solvers are present but not reachable from the dispatcher: distributed_stokes_mumps! (MUMPS factorisation on the patch communicator, matrix assembled at the patch leader) and distributed_stokes_phasebppp! (row-filtered assembly). The gather-to-leader LU of parallel/distributed_stokes_phaseb.jl is the earliest multi-rank-per-patch path.
Iterative tiers
The block-Jacobi preconditioner of :iter and :rich has no coarse-grid correction, so its convergence floor is set by the disjoint blocks (about :phase_a are the tested paths.
Where in the code
| Topic | File | Function |
|---|---|---|
| Dispatcher | solvers/solve_stokes_distributed.jl | solve_stokes_distributed! |
| One rank per patch | solvers/multigrid_stokes_mpi.jl | multigrid_stokes_mpi! |
| Distributed MUMPS | solvers/distributed_stokes_phasebpp.jl, solvers/distributed_stokes_phaseb4p.jl | distributed_stokes_phasebpp!, distributed_stokes_phaseb4p! |
| Distributed FGMRES, Richardson | solvers/distributed_stokes_fgmres.jl, solvers/distributed_stokes_iterative.jl | distributed_stokes_fgmres!, distributed_stokes_iterative! |
| Local grid, halos | parallel/local_grid.jl, parallel/halo_3d.jl | LocalGrid3D, halo_exchange_3d! |
| Memory estimate | utils/dof_estimator.jl | estimate_dofs, estimate_dofs_raw |
| Tests | tests/ | test_mpi_2rank_smoke.jl, test_mpi_phaseb4p.jl, test_mpi_fgmres_b4p.jl, test_assembly_3d_mirror.jl |
References
Amestoy, P. R., Duff, I. S., L'Excellent, J.-Y. and Koster, J. (2001), A fully asynchronous multifrontal solver using distributed dynamic scheduling, SIAM J. Matrix Anal. Appl. 23, 15-41.
Saad, Y. (1993), A flexible inner-outer preconditioned GMRES algorithm, SIAM J. Sci. Comput. 14, 461-469.